Companion to Breaking the 5-Hour Wall (Cline + OpenRouter).
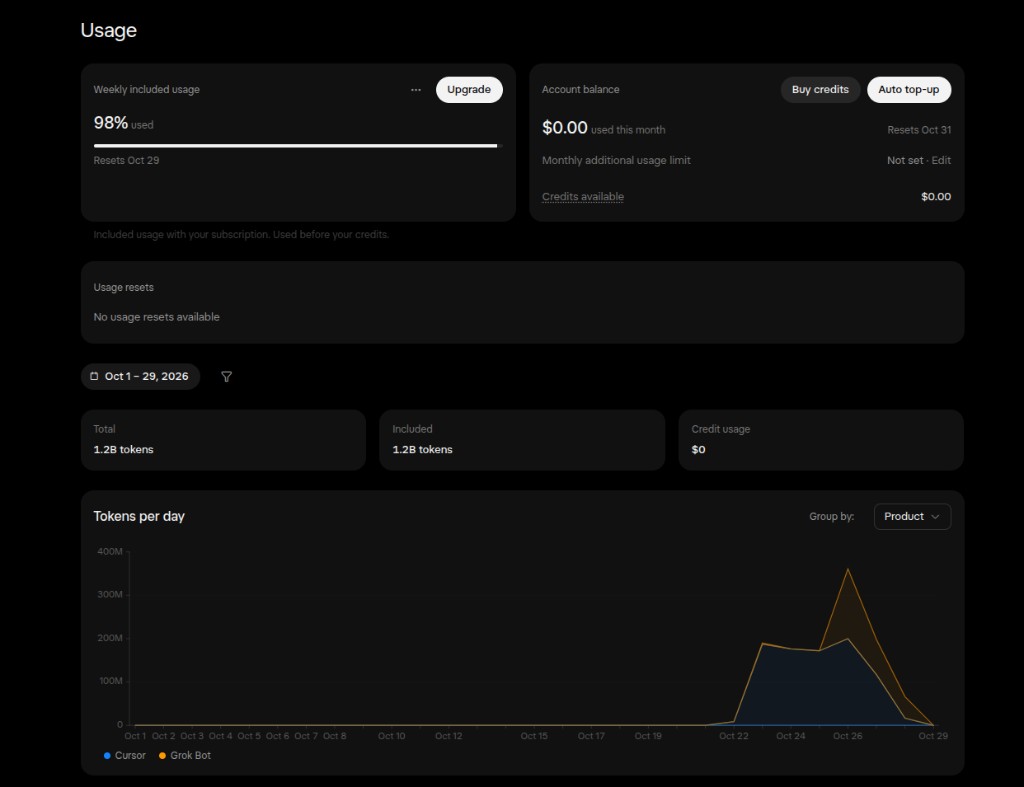
Bottom line: In seven days I billed 1.2 billion tokens, used 98% of my weekly included pool, paid $0 in overages, and ~$50 for the first month of Super ($100/mo after that). I shipped real product: the backend behind CohesionStack Lab, plus Link Preview and the Metadata Packer on production. I also left bots running overnight and watched the meter jump 75% → 82% while I slept. Super is not "unlimited." It is a bigger tank with a weekly drain plug.
If you read the prequel: OpenRouter went $10 → $0 in one night and one thread hit 2.2M tokens before the five-hour wall cut me off. This week the wallet did not empty. The included % did.
The number that actually matters
Cursor bills resends, not "how big your chat feels."
Night one I pulled two numbers from different places (do not mix them on a chart):
- ~530k "last window" tokens across five parent chats still open in Cursor. That is the context size the IDE would send on the next turn in each thread (composer footer / local
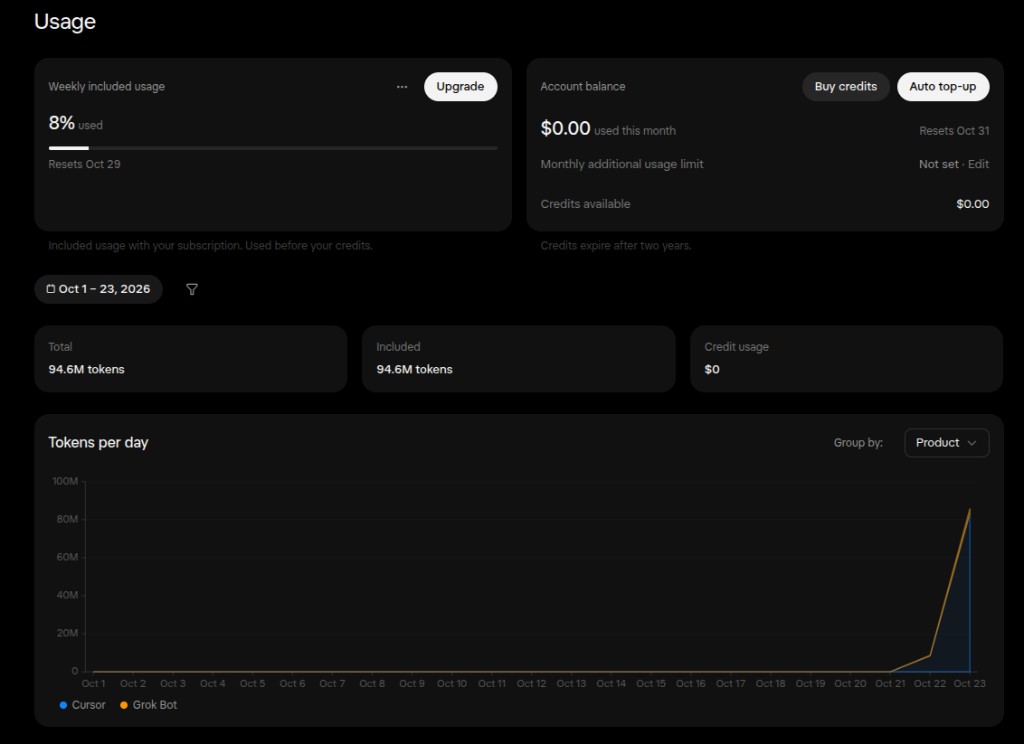
state.vscdbsnapshot from 22 Oct ~11 PM CT, not the Usage page). - 94.6M billed tokens on Settings → Usage for 1-23 Oct (all included, $0 overage).
Billed input is mostly the same windows resent every turn, not one 530k prompt. Rough ratio that night: 94.6M ÷ 530k ≈ 80× (closer to 84× if you add subagent chats, ~1.13M last-window total in the log). Super did not fix that physics. It moved the pain from "declined card" to "why is weekly included at 8% after one evening?"
I still ran the same way: short prompts (proceed, approved, continue), new chats when windows got fat, Composer 2.5 for merges, Grok when Link Preview had two competing interpretations of the same run and needed one resolver, not another CSS tweak.
Cline week vs Cursor week (cheat sheet)
| Cline + OpenRouter | Cursor Super + Grok Bot | |
|---|---|---|
| One thread peak | ~2.2M context | ~200k windows (still hit 63-77% in an evening) |
| Token bill | $10 gone | 1.2B included, $0 overage line |
| Subscription | Pay as you go | ~$50 month one, $100/mo list |
| Stop sign | 5-hour wall | Weekly % (8% → 98%) |
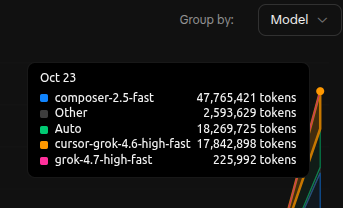
| Chart trap | N/A | Product ≠ Model (orange Grok Bot can own a day) |
What got built
Tue night (22 Oct): Lab infrastructure. Production runs, artifacts, shared browser extraction. The stuff users never see, but Link Preview and Metadata Packer need to show cards, CSVs, and ZIPs instead of placeholders.
Fri-Sat (23-24 Oct): Ship mode on Composer. 23 PRs in a day: Link Preview aligned to mockups, JSON-LD / rich results in the UI, Open Graph plumbing, CloudWatch dashboard in CDK (after I rejected the CLI detour). Weekly 34% → 57%.
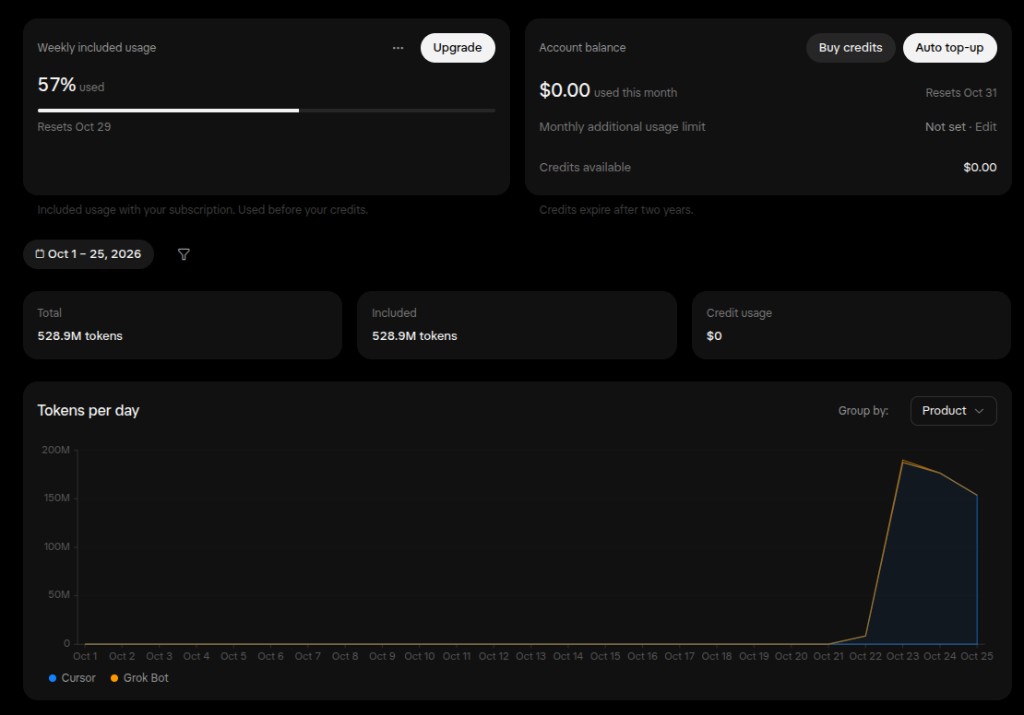
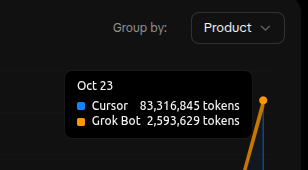
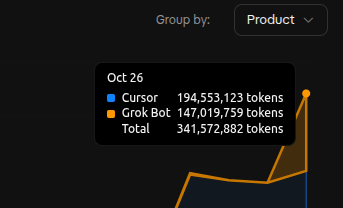
Sun-Mon (25-26 Oct): I tried a four-agent fix (requirements, dev, reviewer, tester), planned the next feature on Grok 4.7, and made the classic mistake: bots kept working after I stopped. 57% → 75% → 82% in about a day. On Oct 26 alone the Product tooltip showed 341.6M tokens, 43% Grok Bot.
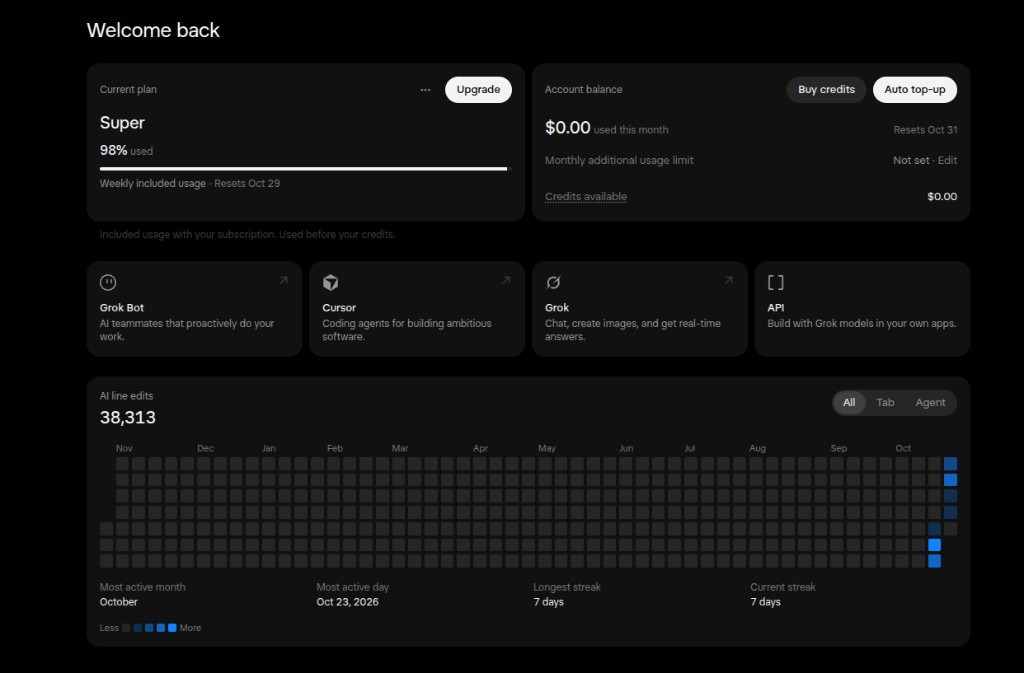
Wed (28 Oct): 98% weekly, 1.2B on the period chart, then I actually closed the tabs. Account page says 38,313 AI line edits and a 7-day streak. Busy week. Not infinite.
Two budgets (learned the hard way on Friday)
LLM tokens and GitHub Actions minutes are both "included until they aren't." On 23 Oct GHA ran out; I deployed production from my laptop instead.
Cursor came to the rescue on CI too. It helped me migrate the entire process from GitHub Actions to my laptop. That only works because I am the solo developer on CohesionStack.
Plan for both meters.
Next week: flatter graph on purpose
I am not trying to repeat the spike. On deck: one new app, a pile of small fixes, SEO/routing work on Lab URLs, and consulting leads to chase. Rules I am actually going to follow:
- Stop background agents above ~70% weekly. Overnight work is a choice, not a default.
- One main lane per day: Composer 2.5 Fast for code (that is the only Composer in the picker). SEO, inbox, and log edits get their own chat on a Medium model (GPT-5.6 Sol, Gemini 4 Argon, Claude Opus 5.5) or Auto, not Grok 4.6 / 4.7 High Fast and not the High Claude/Muse tiers unless the task is hard.
- Batch the small PRs instead of one agent per page.
Goal: stay on $100/mo with headroom, not 98% by Wednesday again.
Notes I wish were in the README
Screenshot Product and Model before you tweet "Grok ate my week." Match model tier to the task (logging on Grok high/fast on day one was dumb). Mockup parity and "does the JSON-LD panel have real data?" are different tests. CDK is the spec for AWS; CLI heroics are undeclared state.
If you want help doing this on your stack
I build CohesionStack and consult on the same workflow: model mix, token vs CI budgets, shipping browser-backed tools without torching the month in seven days.
Describe your challenge or services for a working session.